AI training
Multi-node HGX clusters with NVLink fabric and 400G/800G networking.

Enterprise hardware sourcing · ASTER RACKIT
Accelerated, high-performance and virtualized compute
Browse this section
Browse the AI Training page for product families, configuration notes and quotation paths.
Open page 02Browse the AI Inference page for product families, configuration notes and quotation paths.
Open page 03Browse the HPC page for product families, configuration notes and quotation paths.
Open page 04Browse the Virtualization page for product families, configuration notes and quotation paths.
Open pageCapabilities
Multi-node HGX clusters with NVLink fabric and 400G/800G networking.
Dense PCIe-GPU nodes tuned for throughput-per-watt serving.
High core-count EPYC/Xeon builds with fast NVMe tiers.
Storage-dense ingest nodes with 25/100G connectivity.
Spine-leaf designs with optics and cabling quoted per link.
Power, cooling and cabling validated per rack before dispatch.
How it works
GPU-hours, memory footprint and storage throughput targets.
GPU count, CPU ratio, NVMe tier and network per node.
Node count, fabric topology and rack power.
Cluster-level validation with fabric tests before shipping.
From the facility

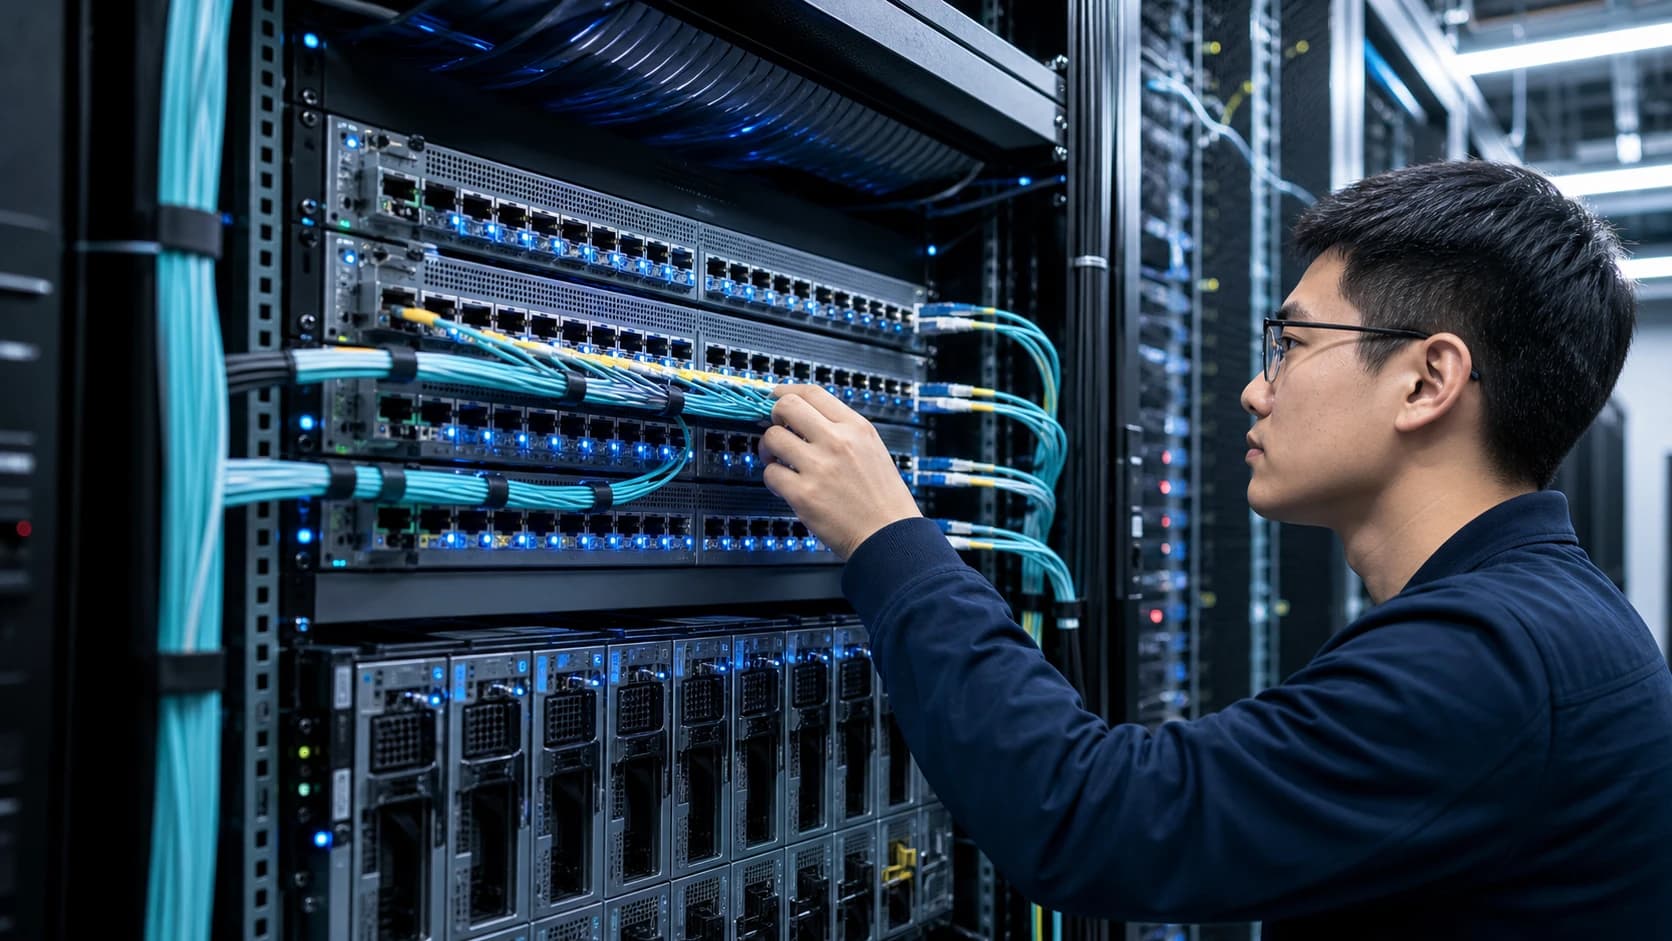


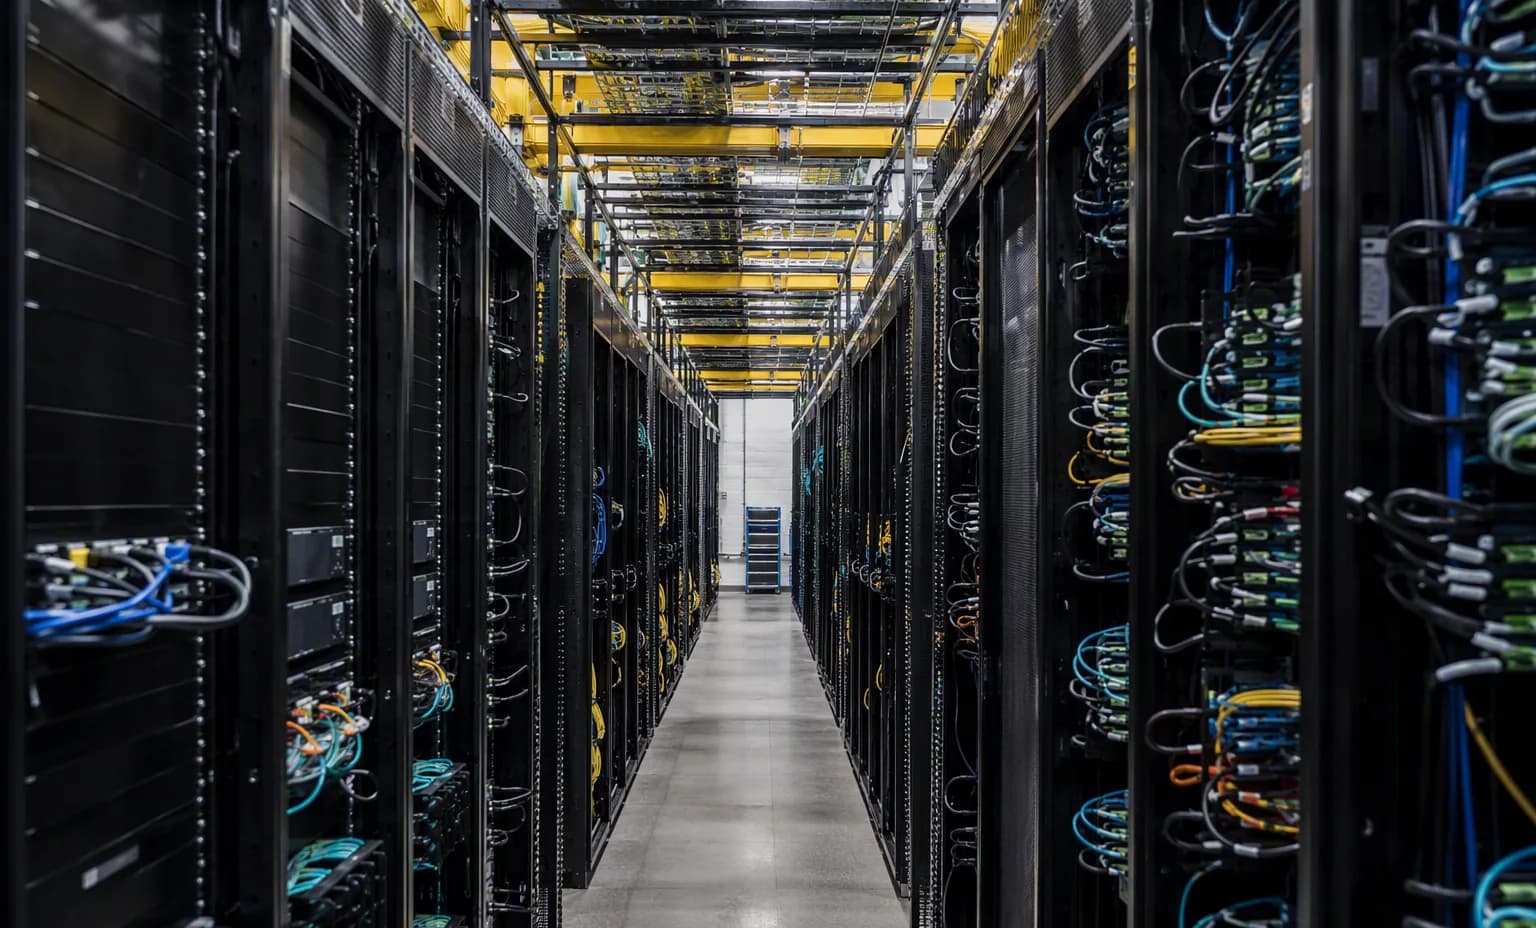
Model, MPN, generation, chassis layout and selected options are separated before a commercial offer.
Factory-new, OEM-program and inspected pre-owned supply paths are shown separately where relevant.
Quantity, accessories, licenses, packing, lead time and delivery route are confirmed before shipment.
Common questions
Up to 8 in HGX/SXM form factors; PCIe designs commonly run 4–10 depending on chassis and TDP.
Multi-GPU training with heavy inter-GPU traffic benefits from NVLink; inference farms often run fine on PCIe.
Yes — per-rack wattage, cooling and PDU specs are included with cluster quotations.
Yes — L-series/RTX-class density nodes for cost-optimized serving are a standard configuration.
Explore the rest of this section
Need an exact model or PN?
ASTER RACKIT can work from a BOM, model list, part number, configuration target or replacement requirement.